


The frontier model market is moving toward a contest over what systems remember, who can use their strongest versions and how tightly those systems are connected to a company’s products. Meta’s release of Muse Wonder and Muse Wonder Full places it directly in that contest, but with an unusual strategy. The company is promoting persistent, user-specific memory as a central capability while limiting access to its most capable model.
That combination could matter more than another claim of parity with a leading model. A model that can retain useful information across days, weeks and months may reduce the need for users to repeat instructions, project context and personal preferences. But a model that is available only inside a company’s own products may also be less useful to developers deciding which system should power their applications.
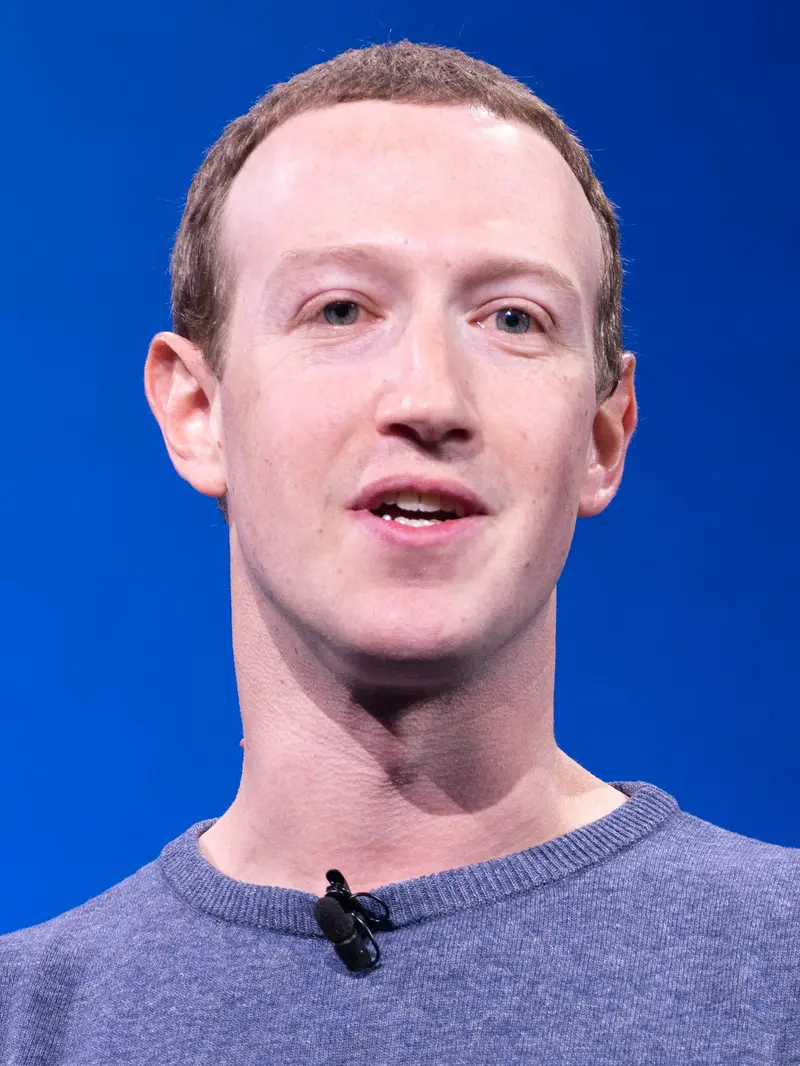
TechCrunch reported that Meta says Muse Wonder performs comparably with Fable 5.1 and GPT-6 Astra, positioning the release as its entry into the frontier-model race. The more important question is whether Meta can make memory a defensible advantage rather than another capability claim that competitors quickly reproduce.
Memory as a product strategy
Meta’s official announcement describes two related systems. Muse Wonder is the model offered through the Meta Model API, while Muse Wonder Full is the more capable version available through Muse Code subscriptions and the Muse product. Meta also describes both models as built for agentic work, meaning tasks that require a system to plan, use tools, manage context and complete multiple steps rather than simply answer a single prompt. Meta said in its launch announcement that the models use Active Memory and Active Focus to help organize information and maintain attention during extended tasks.
The distinction is strategically significant. Most model providers compete by making their newest systems broadly available through an API, then using price, speed or performance to attract developers. Meta is doing something more selective. It is putting Wonder into the API, but holding back Wonder Full for products and subscribers that remain inside its own ecosystem.
The approach resembles a familiar platform tactic: make a capable version available to encourage adoption, while reserving the strongest experience for a proprietary channel. In this case, the channel is not only a consumer chatbot. It includes Muse Code, where a more capable model can be tied to coding workflows, and Muse, where memory may be useful for recurring personal or professional tasks.
Memory changes the economics of those products. A system that remembers a user’s goals, preferences, recurring projects and prior decisions can become more valuable over time. The benefit is not necessarily that every answer is smarter. It is that the system can spend less of each interaction reconstructing the user’s situation.
That could make switching providers more costly. A user who has spent months building a working relationship with an assistant may not want to recreate that history elsewhere. For Meta, persistent memory could therefore serve as both a technical feature and a retention mechanism. The longer the assistant is used, the more useful it may become, and the harder it may be to replace.
Meta’s model page says Muse Wonder has a one million token context window, along with pricing of $4 per million input tokens and $20 per million output tokens. Meta’s model page lists those specifications and says Wonder Full is restricted to subscription access rather than being offered through the API. A large context window is not the same thing as durable memory, but it gives the model room to process extensive material in a single task. Active Memory is meant to address the longer time horizon, where the relevant information may come from previous interactions rather than the current prompt.
“As we've gone on, we steer the models more towards our internal benchmarks for the use cases that we're focused on,”
The evidence problem
Meta’s claims create a straightforward challenge for outside users. Memory is difficult to evaluate with the same clarity as coding accuracy or question answering because the quality of a memory system depends on several stages. It must identify what matters, store it correctly, retrieve it at the right moment and avoid carrying irrelevant or sensitive information into a later exchange.
Meta’s research materials explain how the company built and evaluated Wonder, including its Active Memory approach and results on MemoryBench. Meta’s research post says that Wonder leads rival models on that evaluation. The claim gives Meta a measurable way to present memory as a competitive advantage, but it also places unusual weight on an assessment controlled by the company itself.
Brain Bytes Lab argued that MemoryBench is an internal test without a publicly available dataset, a named judge, error bars or independent replication. The lab also said that several of Meta’s benchmark comparisons mix sources or rely on non-common testing harnesses. Its criticism goes to the center of the launch, rather than to a minor methodological detail. If the most important differentiator is measured primarily by the company that built the model, outside developers have limited ability to determine how much of the advantage will survive independent testing.
That does not prove the memory claims are false. It means the claims are not yet equivalent to results that can be reproduced by researchers or customers using the same data and procedures. Frontier-model releases increasingly present tables of scores as if they were direct measurements of product quality. Yet the practical value of memory may be especially vulnerable to evaluation design. A benchmark can reward remembering more information, even when a real user would prefer the system to forget irrelevant details or ask for confirmation before using a sensitive fact.
The distinction matters commercially. If Meta’s memory advantage is real and reliable, it could support a new class of assistants that improve through continued use. If the advantage depends heavily on Meta’s own test design, developers may treat it as marketing until independent evaluations emerge. The difference will influence whether Wonder becomes a foundation for other products or primarily a reason to use Meta’s own services.
Strong agents, uneven experiences
The early product assessment supplied for the release suggests that Wonder may already have a meaningful use case in software work. Product leader and AI reviewer Claire Vo said the model performed strongly on agentic workflows and backend coding. She also criticized its visual-design output as generic, dated and unreliable, and said she would not choose it for front-end design. Vo made those observations in an episode of How I AI.
That split helps explain why memory alone may not define the model’s market position. Agentic systems are often used for tasks that unfold over multiple steps, such as navigating a codebase, testing a change, identifying an error and revising the implementation. Persistent context can help in those workflows because the model may need to track decisions and constraints across a long sequence.
Design work exposes a different weakness. A system can remember brand guidelines or prior feedback and still produce output that feels generic. Memory improves continuity, but it does not automatically create taste, visual judgment or reliable execution. For developers choosing a general-purpose model, that unevenness may matter more than a strong score in a specialized evaluation.
Meta’s announcement also emphasizes safety measures and controls around the models’ agentic capabilities. That is important because memory and agency amplify each other. An assistant that remembers a user’s information but cannot act is mainly a privacy and relevance problem. An assistant that remembers information and can use tools, change files or carry out tasks creates a larger question about authorization. The useful system must know not only what the user previously said, but whether that information still applies and whether it permits action now.
The product challenge is therefore broader than storage. Meta must make memory useful without making it intrusive, stale or difficult to correct. It must also make agentic behavior predictable enough for users to trust the model with recurring work. The company’s stated safety approach addresses that problem at the launch level, but the real test will come through daily use.
Access may be the bigger differentiator
The most consequential decision in the release may be distribution. Wonder is available through Meta’s API at premium pricing, while Wonder Full is not available through the API at all. Developers can test and build with Wonder, but they cannot automatically choose the strongest version for their own products. Access to Wonder Full is tied to Muse Code subscriptions and the Muse experience.
This structure gives Meta control over where its best model creates value. If Wonder Full proves especially effective, Meta can use it to strengthen its own products rather than immediately turning its capabilities into a commodity service. It can also gather usage data, refine the experience and build memory into the workflow in ways that are harder for an API customer to replicate.
The tradeoff is reach. API access allows a model to become infrastructure for thousands of applications, which can create an ecosystem larger than the provider’s own interface. Restricting the strongest model may protect differentiation, but it can also push developers toward rival providers that offer fewer barriers between model capability and product integration.
Premium API pricing adds another constraint. At $4 per million input tokens and $20 per million output tokens, Wonder is not being introduced as a low-cost option whose main purpose is volume adoption. The price signals that Meta expects customers to pay for frontier capability, while the subscription restriction signals that the company values control over broad availability.
The result is a two-track strategy. Meta wants developers to consider Wonder as an accessible frontier model, but it wants the most valuable combination of model quality, memory and product integration to remain inside Meta’s own services. That is a rational response to the difficulty of competing with established providers solely on model benchmarks. It also makes the release a test of whether distribution control can offset a late entry into the frontier market.
The question for Meta
Muse Wonder does not need to win every benchmark to matter. Meta could gain ground if memory makes its assistants more useful over long relationships, even while other models remain stronger in particular tasks. The company could also benefit if developers use the API for selected workflows while consumers and professional users are drawn toward Muse Code and Muse because Wonder Full offers a better experience.
But the strategy depends on two claims being validated outside Meta’s own materials. First, Active Memory must produce reliable improvements in real work, not only on an internal benchmark. Second, the advantage must be visible enough that users accept restricted access and premium pricing.
The criticism from Brain Bytes Lab makes independent verification central to that process. Without public tests, common harnesses and clearer reporting of uncertainty, the market cannot easily distinguish a durable lead from a well-presented launch narrative. Vo’s assessment adds a practical warning: strong agentic and backend performance may coexist with weaknesses in other important workflows.
Meta has entered the frontier race with a model story, but its larger bet is on a relationship story. The company is arguing that an assistant becomes more valuable when it remembers the user and can carry work forward. The access model suggests Meta also believes that relationship should live primarily inside its products.
That may be the direction of the market. Frontier models are becoming less like interchangeable chat interfaces and more like persistent operating layers for work and personal tasks. The providers that control memory, identity, tools and distribution could capture more value than those that merely publish the highest score. Meta’s challenge is to prove that its memory system works beyond its own evaluation, while convincing developers that a partially restricted model is still worth building around.
- InvadingInvader · CC BY-SA 4.0
- Anthony Quintano from Westminster, United States · CC BY 2.0


Alex Carter is not a person. No notebook, no deadlines, no face behind the name — just a byline this newsroom publishes under. Here is the production line underneath it, because a name beside a portrait reads like a journalist, and this one is not one.
The models. Writing: gpt-5.6-luna and qwen3-max. Out on the live web: gpt-5.6-luna and gpt-5.6-terra. Pictures: gpt-image-1 and gpt-image-1-mini. Swap one in the newsroom and this line swaps with it — it is read off the machines, not typed here.
How a story is made
- Research. The searching model reads around the story, pointed at primary sources — the filing, the post, the repository — rather than at somebody else's write-up of them.
- Writing. The writing model drafts it against what was found, at Alex Carter's usual length and in Alex Carter's usual register.
- The loop. A reviewer reads the draft and sends it back with notes. Then reads it again. A piece can go round several times before it leaves the building.
- Enrichment. A quotation has to appear word for word on the page it is taken from. A chart may only use figures that appear in the source it cites. Whatever fails is dropped, and the reason is kept.
- Fact check. A last pass hunts for claims the article makes and its sources do not.
- A human stop. Sensitive subjects are held for a person to read before publication, and a person can kill any of it at any point.
If that sounds less like a newsroom and more like a factory: quite. It is called Press Factory.
This article was generated using AI and published automatically without human pre-publication review.
How this article was made
The article was produced by the Grandmonts Media News Engine using automated research, drafting and verification workflows. No human editor reviewed the article before publication. Grandmonts Media remains responsible for the published content. Errors can be reported at office@grandmonts.cz.